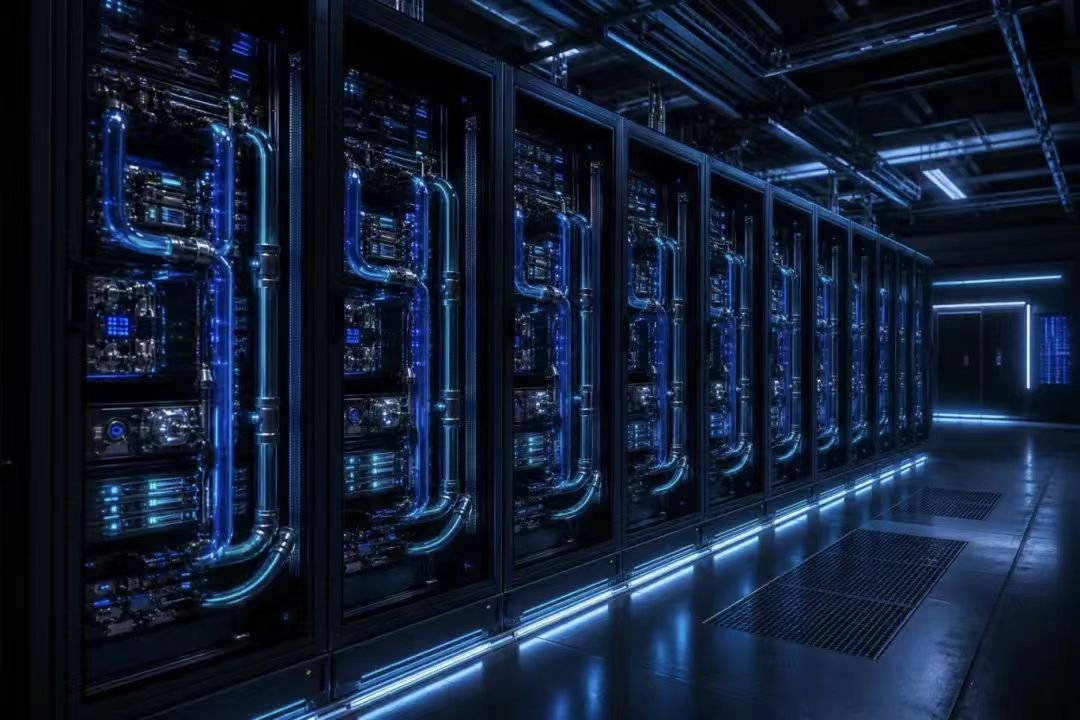
Our direct-to-chip liquid cooling manifold and piping system, engineered and manufactured in China, forms the critical fluid distribution backbone for high-density AI accelerators and GPU server clusters, delivering precision coolant routing between CDU skids and server-mounted cold plates. Purpose-built to address the non-uniform heat flux and stringent flow-balancing requirements of next-generation compute hardware, this integrated flow assembly eliminates thermal maldistribution across parallel server sleds and individual cold plate circuits, maintaining tightly controlled thermal setpoints even under sustained training and inference workloads. Designed for both hyperscale greenfield deployments and brownfield liquid cooling retrofits, the portfolio combines rigorous domestic manufacturing capacity with internationally aligned thermal and hydraulic standards, offering global operators a reliable, cost-competitive fluid conveyance solution for scaling direct-to-chip cooling infrastructure.
The engineering package encompasses custom manifold hydraulic design, CFD flow simulation, material qualification, prefabricated piping assemblies, quick-disconnect coupling integration, pressure drop validation and full circuit compatibility testing with deionized water and formulated secondary coolants. Fabrication leverages precision welding, CNC machining and clean assembly protocols for stainless steel and high-purity polymer flow paths, with every branch port calibrated to deliver matched flow rates and pressure differentials across the rack array. Configurable in-rack, rear-door and row-level manifold layouts, the system supports modular phased expansion, standardized interface dimensions and flexible routing geometries that adapt to proprietary server chassis, OCP-compliant hardware and site-specific utility constraints. All assemblies undergo hydrostatic leak testing, particulate cleanliness inspection and dimensional verification prior to shipment to reduce on-site fit-up risk.
This engineered manifold and piping architecture unlocks tangible operational resilience and efficiency gains for AI data center operators. Balanced parallel flow distribution suppresses hotspots, prevents GPU thermal throttling and preserves consistent compute throughput as rack power densities climb well beyond air-cooling limits. Zero-spill quick connect interfaces enable hot-swap server replacement and maintenance without draining the entire secondary loop, cutting service downtime and lowering technician exposure to fluid hazards. Closed fluid circuit construction protects cold plate microchannels from particulate contamination, extending component service life, while compatible sensor taps support real-time flow, temperature and pressure telemetry for DCIM and BMS integration, laying the foundation for predictive cooling fleet management and optimized PUE performance.
We deliver full-lifecycle technical support extending from conceptual hydraulic layout and P&ID development, factory fabrication supervision and FAT, through site installation guidance, loop flushing and commissioning validation. Our China-based engineering and production team aligns manifold performance envelopes with upstream CDU specifications and downstream cold plate requirements, bridging cross-vendor interface gaps and reducing coordination overhead for international EPC partners and data center owners. By merging scalable manufacturing capability with application-specific thermal engineering expertise, the solution offers a dependable, lead-time optimized flow distribution platform that supports the global acceleration of direct-to-chip liquid cooling adoption across AI, HPC and high-performance enterprise compute facilities.