
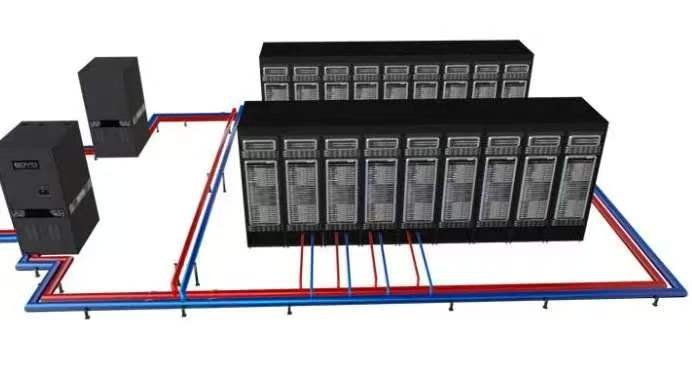
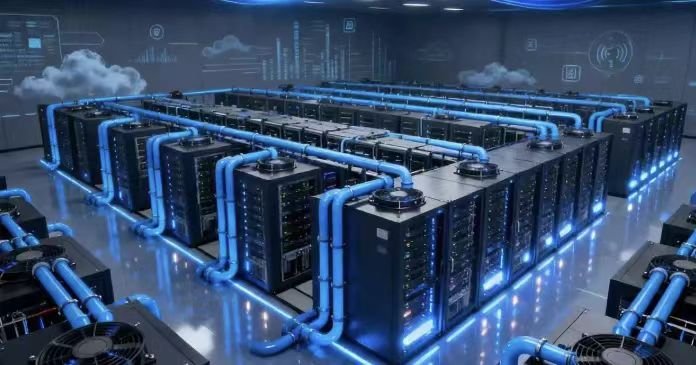
Our direct-to-chip liquid cooling manifold engineering delivers mission-critical fluid distribution infrastructure tailored for high-density GPU clusters powering large language model training, inference and HPC workloads. Purpose-built to bridge CDU and GPU cold plate assemblies, the manifold acts as the core fluid routing backbone, resolving thermal bottlenecks that limit rack power density in hyperscale AI deployments. We integrate deep thermal hydraulics expertise with data center operational requirements, offering custom manifold design, flow balancing simulation and full engineering consultancy aligned with modern AI hardware roadmaps.
The manifold architecture is engineered for uniform coolant distribution across multi-GPU trays, featuring precision-machined flow channels, leak-tested blind-mate quick disconnect interfaces and modular port configurations compatible with HGX, NVL and other mainstream GPU form factors. Computational fluid dynamics (CFD) simulation is embedded throughout the design cycle to minimize flow maldistribution, pressure drop and hot-spot deviation across the entire cluster. Material selections cover stainless steel and high-performance engineered polymers, with full pressure cycling, corrosion and cleanliness validation to meet stringent liquid cooling infrastructure standards for continuous 24/7 operation.
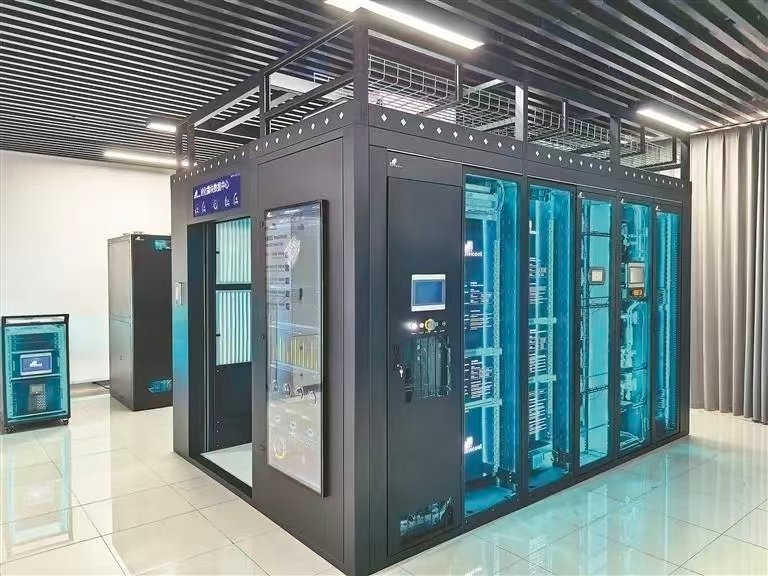
This engineered manifold system unlocks substantial operational advantages versus conventional fluid distribution layouts. By stabilizing inlet flow and temperature to every GPU cold plate, it maintains consistent thermal resistance even at rack power levels exceeding 100kW, eliminating performance throttling during sustained heavy compute tasks. The modular skid-ready construction shortens on-site installation and commissioning timelines, while built-in pressure sensing and leak detection interfaces enable real-time health monitoring. Reduced pumping power requirements further optimize PUE and lower long-term energy expenditure for hyperscale operators.
We provide end-to-end manifold engineering spanning conceptual design, prototyping, factory FAT testing, site integration and lifecycle technical support for global AI infrastructure owners and EPC contractors. Every manifold solution is optimized for scalability, allowing seamless cluster expansion without reworking primary fluid loops. Our engineering team collaborates closely with server and CDU vendors to ensure full interoperability, mitigating deployment risk and supporting reliable, high-uptime GPU clusters for enterprise AI and hyperscale data center projects worldwide.
